 by
Teams that use AI need a shared place for facts, source files, and project notes. This guide shows how to build that base, keep it up to date, and use it for real work. Choose what can be shared in public and keep private records where they belong.
This guide is part of How Our AI Agents Share Memory and Coordinate Work. Next, explore How We Build and Maintain AI Agents, or What You Are Installing: The Local Service Spotlight Claude Plugin Explained.
Where this task fits in the Content Factory
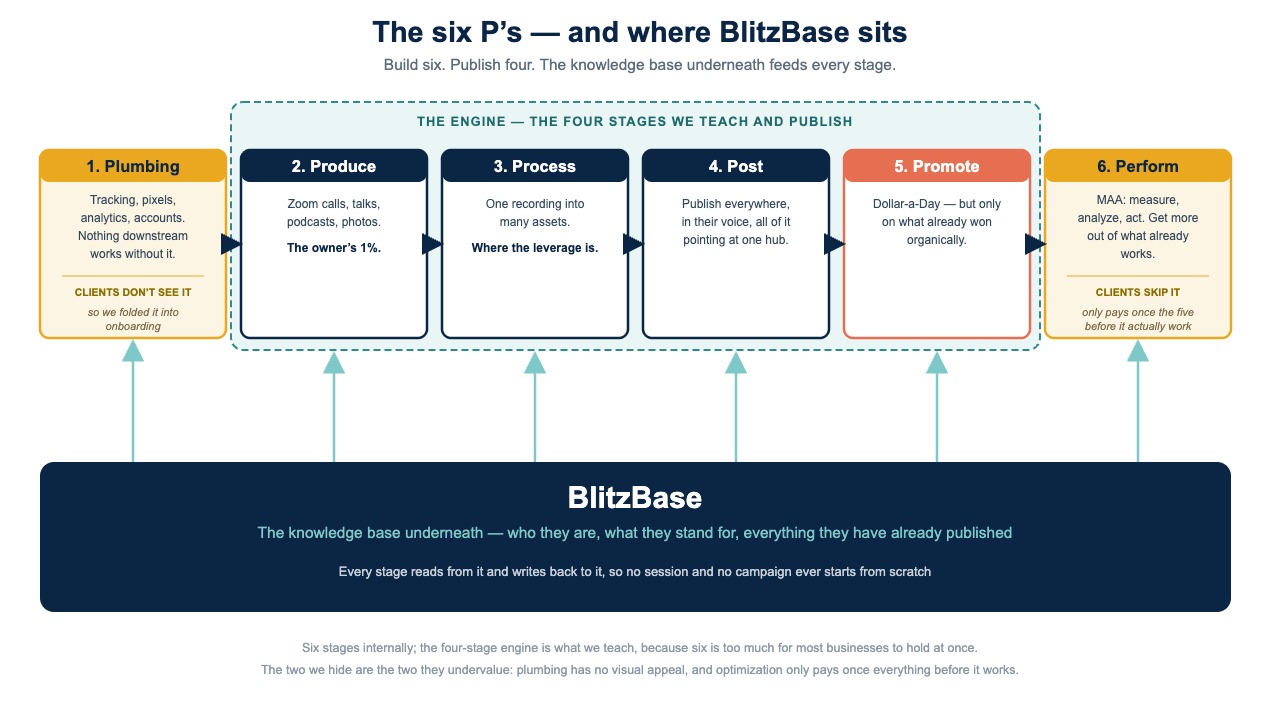
This task supports work across the Content Factory (our four-stage process for using real content). Its inputs and next handoff determine which stage uses it. This playbook coordinates several smaller tasks. Use each linked recipe for its detailed steps.
1. ProduceCapture real work
2. ProcessTurn sources into useful assets
3. PostPublish and connect approved assets
4. PromoteShare proven work and measure results
Start, finish, and next step
- Start when
- A person or client needs one source-backed knowledge base for ongoing work.
- Have ready
- Confirmed GCT (Goals, Content, Targeting: the goal, material, and audience)
- Authorized website, social and transcript sources
- Separate raw, compiled and deliverable storage
- The applicable privacy and source-authority rules
- Follow the steps
- Build the personal or client corpus
- Derive voice, topics, context and entity facts from evidence
- Read the base at session start and update it at wrap-up
- Publish only approved public-safe outputs from the base
Use the detailed instructions in this article for each step.
- Finish with
- A maintained knowledge base with traceable facts and a record of what each session shipped or learned.
- Measure the result
- Raw sources remain distinct from compiled records
- Voice and entity facts trace to real material
- Session updates preserve current status and provenance
- Public outputs omit private files and metrics
- Hand off next
- Use the base in subsequent task runs; approved public outputs follow the meta article (a record of one task run) and publishing recipes.
- Only for approved public-safe output after writing and editorial checks: step 12 post article on wordpress
Reference material for the inputs
Related tasks
Open this article’s tasks in the Task Library (our directory of tasks and recipes; see current Task Library). The library connects the current recipe, its smaller tasks, and the records of work performed.
Close the learning loop. Write a meta article: the record of this execution with the starting state, recipe version, result, checks, failures, and next owner. Link it back to this recipe and register the run under the same Task Library task. Reuse one execution ID for revisions and retries. A partial or failed run stays labeled that way. Public release follows the recorded publication authority; writing the run record is part of doing the task. Writing and revising that record belong to the original execution; they do not start another meta-article task. Use the findings to propose and verify a recipe improvement. See how recipes and execution records work together.
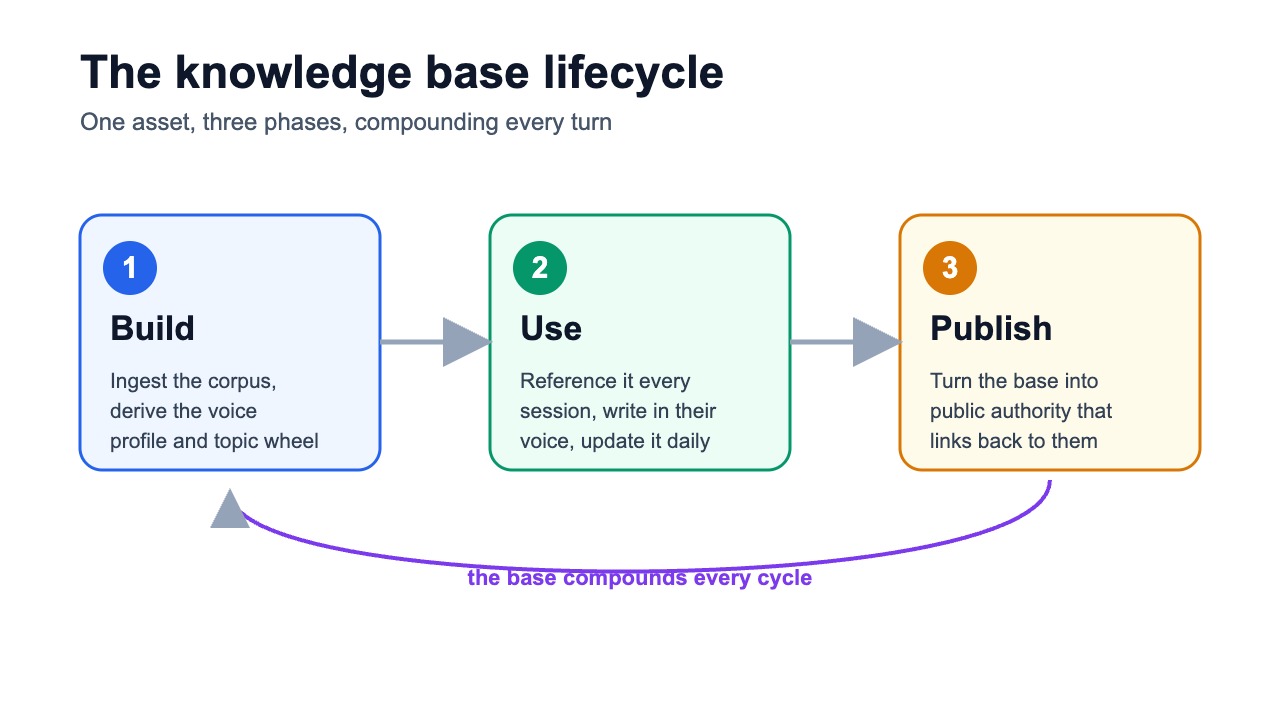
A knowledge base is the difference between an AI agent that starts every task from scratch and one that already knows who a person is, what they stand for, what they are trying to do, and where the project stands. Build it once and every future session inherits it. This is the definitive guide to the three phases that matter, build the base, use it every session, and publish public authority from it, and it ends with a runbook you can hand straight to your own agent. The system we use to do all of this is BlitzBase, our installable AI knowledge base, and the worked example throughout is a real build: Paul Ryazanov’s ecommerce knowledge base, which now backs more than 170 published articles.
This sits on top of the Content Factory and uses the same entity-authority mechanic Dennis Yu lays out in Google Entities and Trust and Own Your Name on Google. Those explain why entity signal matters. This explains the asset that produces it. It is also the companion to how we build AI agents and keep them current and how coaches turn their content into agents: those cover the agents, this covers the knowledge base the agents read from.
What BlitzBase Is
BlitzBase is the installable version of the internal knowledge system we run real marketing work through: articles, content repurposing, weekly client reports, Dollar-a-Day campaigns, Knowledge Panel work, website audits. You clone it to your Mac once and your Claude stops being a chatbot and starts being a teammate that already knows the methods, the clients, and the voice. It is the packaged, shareable version of the private system we use in production.
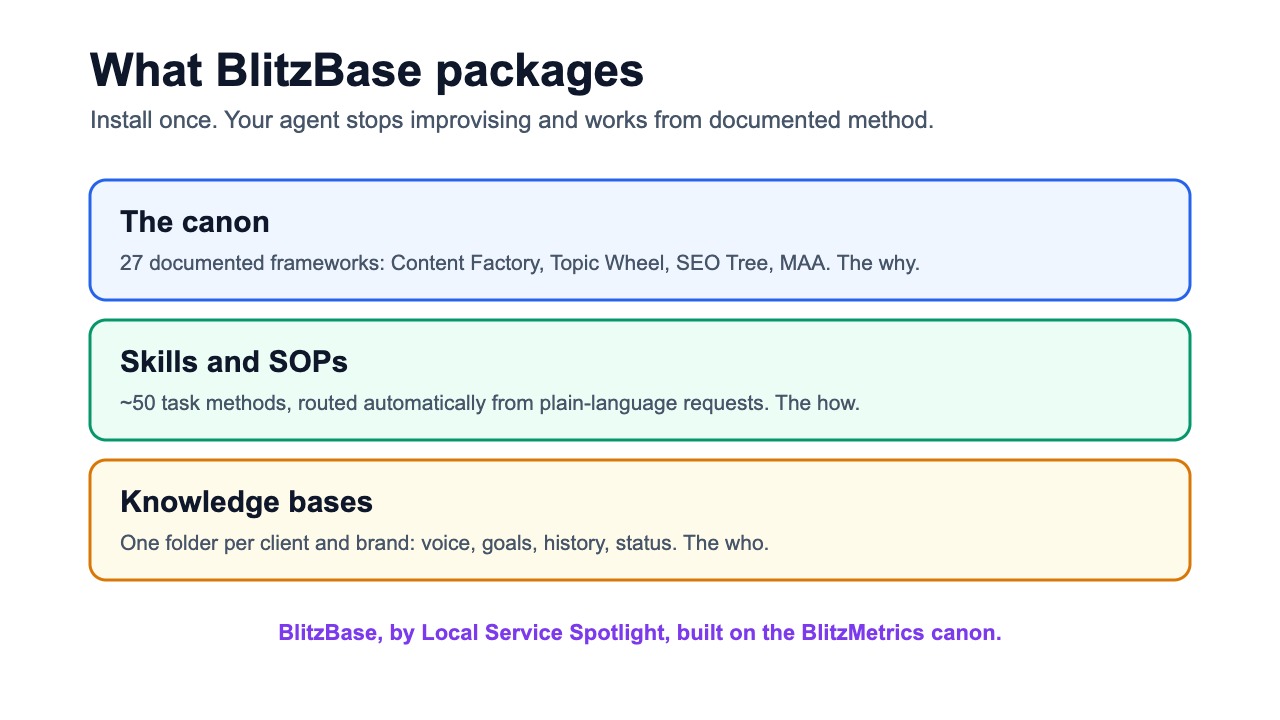
It packages three layers. The canon is the documented methodology, published openly on BlitzMetrics, so your agent cites a real framework instead of improvising one. The skills and SOPs are step-by-step methods for around 60 task types, routed automatically when you ask in plain language. The knowledge bases are one folder per client and per brand you run, holding their voice profile, site rules, history, and live status, built by the agent itself from their website, socials, and transcripts. The result is that you say “turn this post into an article for my client’s site” and the agent already knows the client’s voice, which site it ships to, what the guidelines demand, and what existing content to link into.
The full repo is private and invite-only, distributed through our team, the AI Builder Program, or a client or partner relationship. If you want the method in miniature first, the BlitzBase home page has a free Quick Start you can run in free Claude in about a minute, no install required.
Why a Knowledge Base Beats Starting From Scratch
Most people already have more than they think: a website, years of social posts, recorded talks, guest appearances, client stories. Scattered, none of it works after the week it went out, and any agent picking up a task has to re-derive what was already known or, worse, gets misled by a single stray email or a stale record in a connected app.
A knowledge base fixes that by being the one source of truth for the entity: the voice profile, the content corpus, the goals and target audience, the topic wheel, and the current project context. Because it exists, a new session references the same profile every time instead of guessing. It does not redo finished work and it does not get confused by a random input it happens to see.
Read the compiled knowledge base first to recover context, then verify changeable facts in the system that owns them. The current authorized request and applicable safety and permission boundaries take precedence over stored context. A new email or live dashboard can reveal that a stored fact is stale; preserve the evidence, resolve the conflict, and update the base instead of treating either copy as automatically correct. See the shared-memory authority rules.
Phase One: Build the Base
After you install BlitzBase, building a base is two plain-language requests. First, “set up my personal knowledge base,” with your website and socials. Second, “set up a new client knowledge base for [name],” with their site and socials. The agent scrapes the site and social archive, pulls video transcripts, and builds a folder that knows who they are and how they talk. The personal step comes first on purpose, because it is what makes everything afterward sound like the person instead of like AI.
Under the hood the goal is one structured place where every fact traces back to a source. Start with goals, not content. Capture the person’s Goal, Content, and Targeting first, because that drives every downstream decision about what to write and who it is for. Then ingest the full corpus. Pull the website down page by page, export and catalogue the social archive, and transcribe every talk so spoken words become searchable text instead of staying locked inside video. For Paul that meant 340-plus site posts and pages, 245 usable LinkedIn posts, and 46 recorded talks, all in one place for the first time.
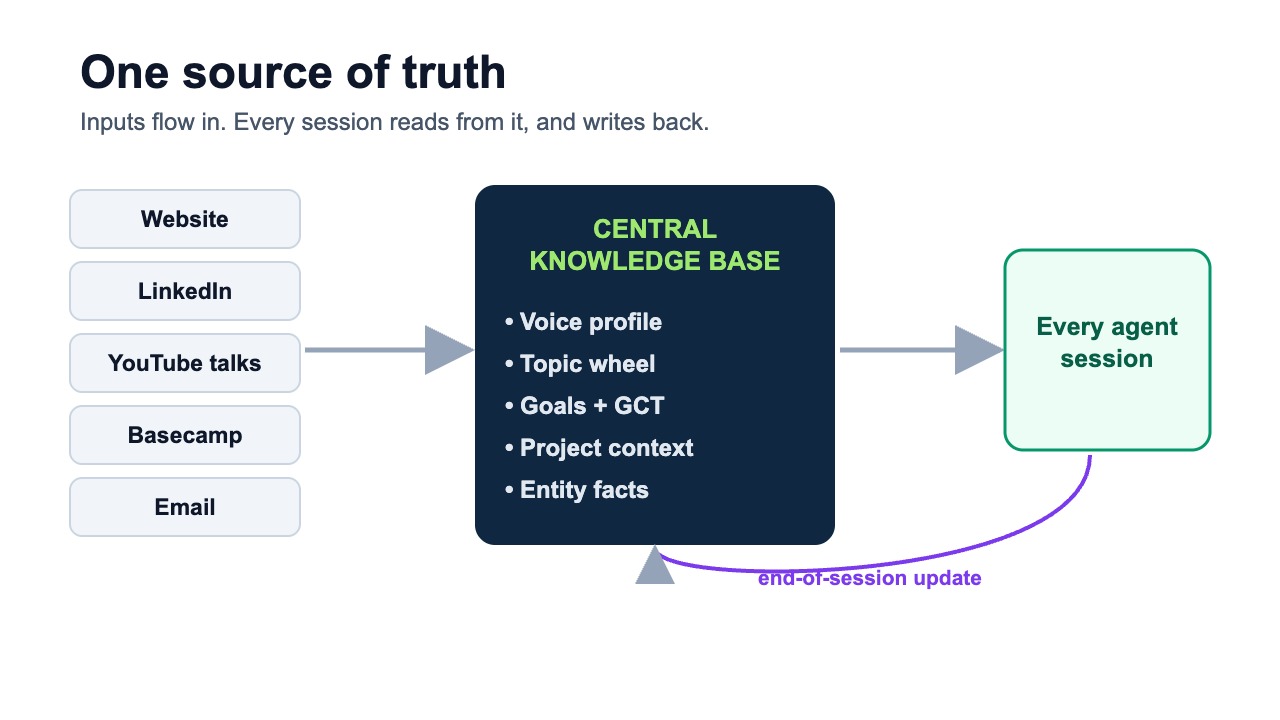
The folder convention keeps it honest: raw material stays separate from the compiled reference documents, which stay separate from finished deliverables, so provenance is never lost. From that corpus the agent derives the four assets that make the base usable, and derives them from the real material, not from imagination:
- A voice profile built from real transcripts and shipped writing, capturing how the person actually writes so the output reads like them and not like a chatbot.
- A topic wheel of the authority clusters the person genuinely covers. This is the analysis step that turns a pile of posts into a strategy and shows a specialist where a scattered feed looked like a generalist.
- Goals and project context: where the engagement stands, what is blocking it, and what has already shipped.
- Entity facts: the bio and schema truth for the person, so the same details show up everywhere.
Phase Two: Use It Every Session, and Keep It Current
A base is only worth building if it is referenced every time and updated every time. Both halves are non-negotiable, and in BlitzBase they are the one rule the whole system depends on: start in the base, end in the base.
Reference it at the start of every session. Before looking anything up about the person, the agent reads the base first. Use it for context, and verify changeable facts against the authoritative source when they matter to the task. Draft in the person’s real voice by loading their voice profile before writing a single line, because voice is specific to each person and each site, and content that does not match the profile is a defect, not a style choice.
Update it at the end of every session. When the work is done you say “wrap up,” and the agent logs what shipped and what it learned back into the base, so the next session starts smarter than the last one ended. Shipped an article, its URL gets logged. Learned the client hates exclamation points, that goes in their voice profile. This is the habit that makes the system compound while ordinary AI setups stay frozen.
Capture new information the moment it arrives, so nothing is lost. Connect Drive, Gmail, and Calendar as raw inputs the agent can pull live specifics from, checking conflicts against the current request and the system that owns the fact before updating the compiled base. The strongest version of this is to pipe the tool that carries your project signal straight into the base. If your client work lives in Basecamp, the Basecamp integration flows your project threads and check-in replies into the knowledge base on a daily sync, set up by your agent in about five minutes, and the full build behind it is documented in how we connected Basecamp to BlitzBase. A fact that lives only in an inbox is a fact you will eventually lose.
Phase Three: Publish Authority From It
Once the base is mature, it becomes the input to public assets that make the person real to Google and to AI assistants. The pattern we use is three interlinked articles, and it is worth understanding why it is three and not one.
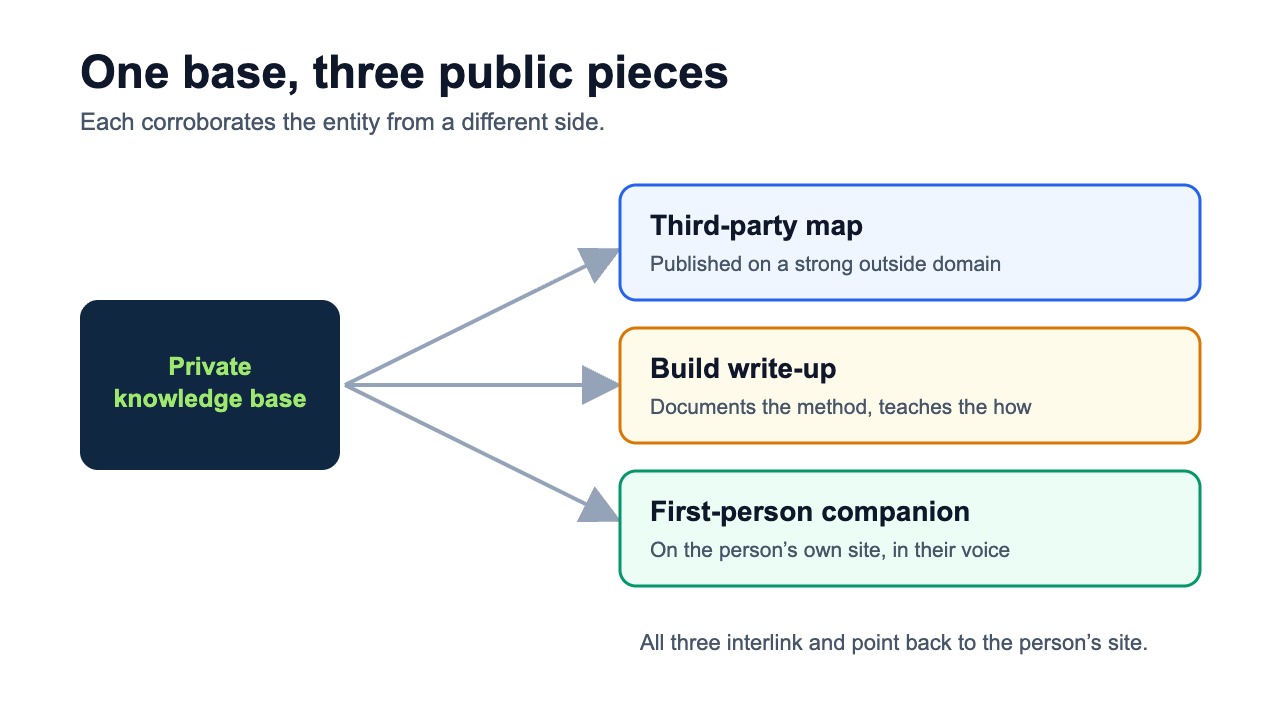
The first piece is a public map of what the knowledge base contains, published on a strong third-party domain. The second is a build write-up that documents the method. Both pass a followed link from an authority domain to the person’s own site. The third is a first-person companion published on the person’s own site, in their voice, from their own angle. It corroborates the same facts from the first-party side without competing with the third-party map as duplicate content. For Paul those are the public knowledge base map, the full build write-up, and his first-person companion.
The interlinking is the actual leverage. Because the base has read every post, each new article links into the existing library with descriptive anchor text, and every piece strengthens the others instead of adding noise. Set the author byline explicitly every time, the person on their own site and your brand on yours, and describe the work honestly. Say that you use the base to repurpose existing content and interlink it. Do not invent a cadence, and keep only true, stable numbers. The build itself follows our meta-article method and publishing guidelines.
What Stays Private
Publishing from the base does not mean exposing the base. Public articles talk about what you produce; they never expose the internal files or private numbers behind it. This line is not optional.
Safe to publish: the public content-inventory counts, the topic wheel, the method itself, and the person’s own public quotes. Never publish: internal project threads and client communications, weekly reports and their SEO figures, the vault and raw files themselves, credentials, and private dashboards. The test is simple. If it describes public content the person already put into the world, or the method you use, you can talk about it. If it is an internal file, a private metric, or a private conversation, it stays in the base.
Give This to Your Agent
Everything above is a method a capable agent can run end to end for a new person. Install BlitzBase so the agent has the canon, skills, and folder conventions, then hand it the runbook below. It works the same whether you use Claude Code or the friendlier Claude Cowork desktop app.
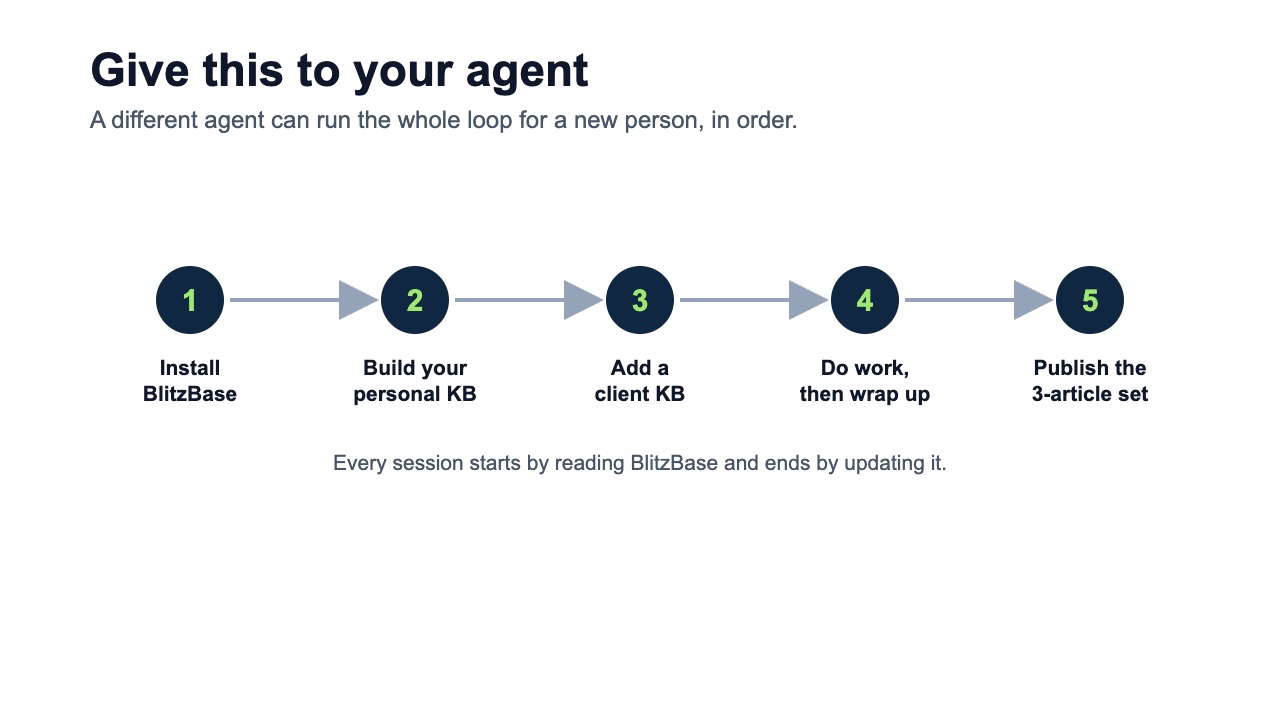
The steps, in order:
- Install BlitzBase. Clone the repo to
~/Documents/Claude/BlitzBaseand run./setup.sh. In Cowork, paste the one memory rule from the BlitzBase home page and save it to memory so every session starts by reading the base and ends by updating it. - Build the personal knowledge base. Tell the agent your website and socials and have it scrape them into a voice profile, topic wheel, goals, and entity facts. Do this first so everything afterward sounds like the person.
- Add the client or subject. Give the agent the subject’s site and socials and have it build their folder the same way, starting from their Goal, Content, and Targeting.
- Connect the project feed. Optionally set up the Basecamp integration so new project context flows into the base automatically instead of getting retyped.
- Do the work, then wrap up. Ask for real tasks in plain language, and end every session with “wrap up” so what shipped and what was learned goes back into the base.
- Publish the three-article set. When the base is mature, publish the map and build write-up on a strong third-party domain under your byline, and the first-person companion on the subject’s own site under theirs, all interlinked, keeping everything internal out of public view.
Here is a prompt you can paste to an agent that already has BlitzBase installed:
Read BlitzBase first (claude-code/CLAUDE.md, then the relevant skills). We are building a public knowledge base for [PERSON], whose site is [URL] and socials are [LINKS]. Step 1: set up my personal knowledge base if it does not exist yet. Step 2: set up a client knowledge base for [PERSON] by scraping their site, socials, and video transcripts into a voice profile, topic wheel, goals and GCT, and entity facts. Step 3: if they use Basecamp, connect it so project threads sync in. Step 4: repurpose one of their existing posts into a full article in their voice, interlinked into their library, published under their byline with full SEO. Step 5: when the base is mature, publish the three-article package (third-party map, build write-up, first-person companion) with correct bylines. Follow the BlitzMetrics publishing guidelines, never expose internal files, reports, or private metrics, and wrap up by updating the knowledge base at the end.
The Base Compounds
Build gives you the asset. Use keeps it accurate and on-voice and feeds every new fact back in. Publish converts it into authority that links back to the person. Each turn makes the next one cheaper and stronger, because the corpus deepens, the voice sharpens, and the entity consolidates into one findable, recommendable person.
If you want the method behind the signal, start with Google Entities and Trust. If you want the system that runs it, install BlitzBase and connect it to your project work with the Basecamp integration. If you want to see the finished result, Paul Ryazanov’s site grows from his base. The same system runs for anyone who has already done real work and wants it to compound instead of disappear.
Originally published .
Dylan Haugen
Dylan Haugen is a professional dunker, content creator, and editor at the Content Factory, where he transforms podcasts and interviews into strategic brand assets. He collaborates with Dennis Yu to support young entrepreneurs and business owners in building their personal brands through education, transparency, and effective content marketing. As the host of the Dunk Talk podcast and a dedicated advocate for establishing dunking as a recognized sport, Dylan combines athletic expertise, storytelling, and digital strategy to help elevate the next generation of creators.